
End State
At the end of this guide you will have:- a
cake-agentsHelm release deployed to your cluster - a reachable control plane UI/API
- a database connection (embedded Postgres for development or an external database)
- session pods launching successfully in the expected namespace
Architecture Summary
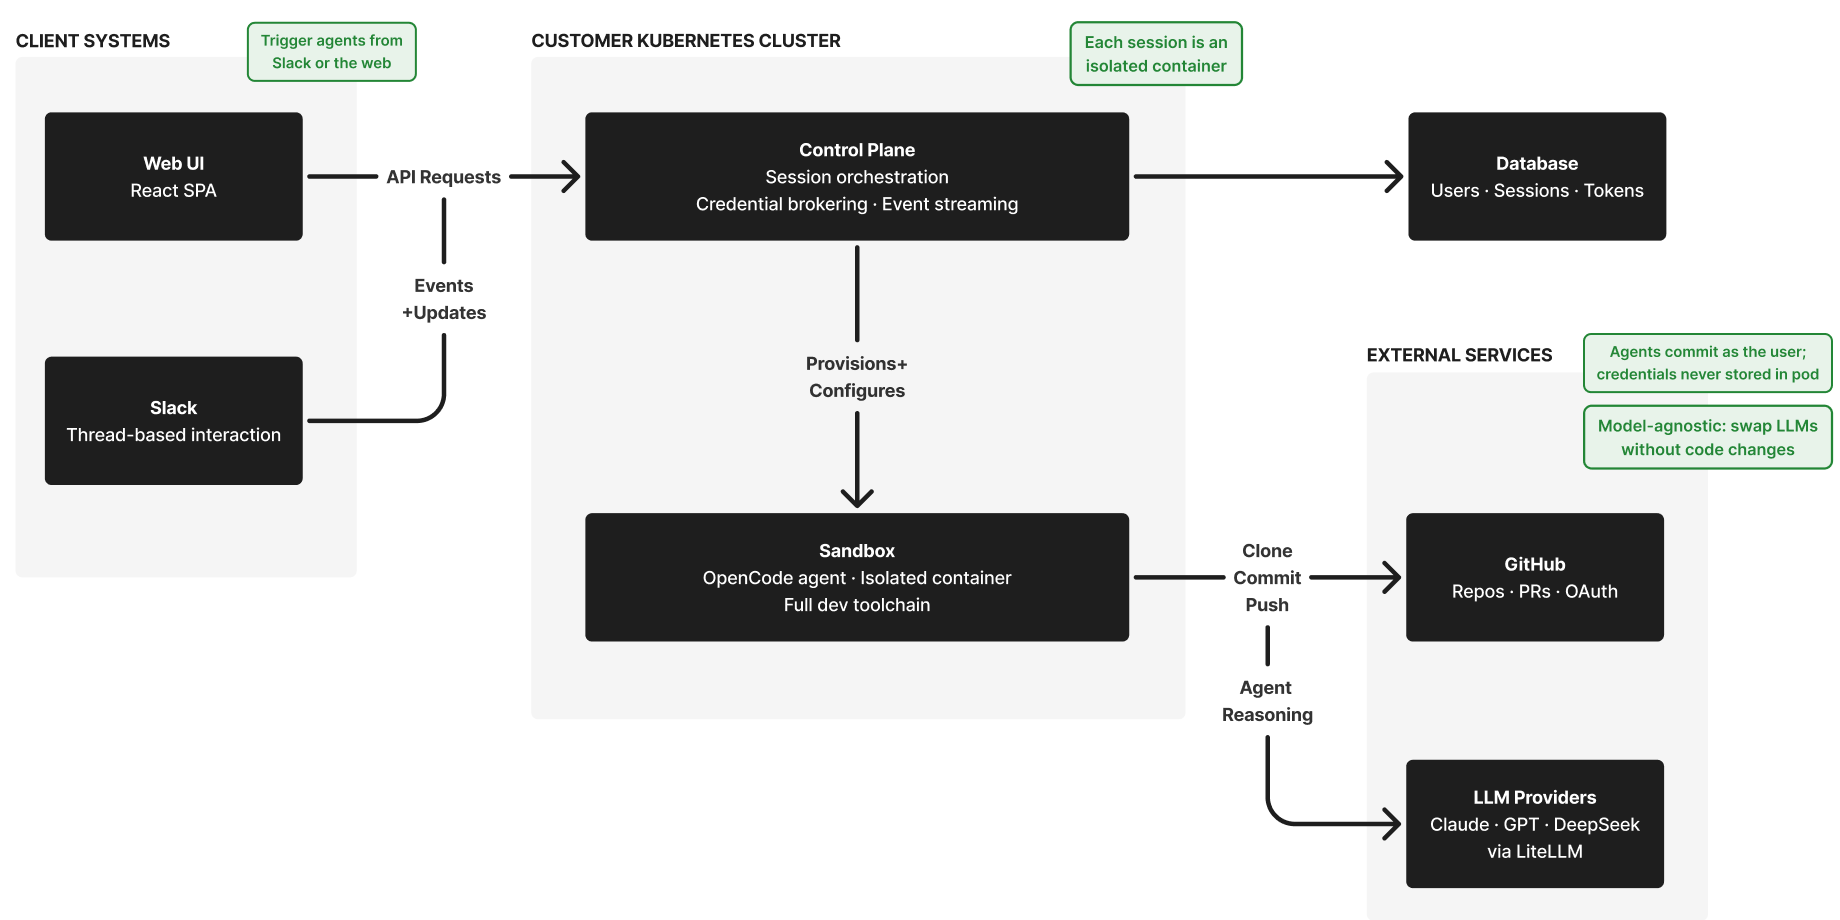
- The control plane is a web application deployed as a standard Kubernetes workload.
- Each user session launches a data plane pod that runs OpenCode inside the cluster.
Prerequisites
- A working Kubernetes cluster
kubectlconfigured for the target clusterhelm3+- A DNS name for the control plane
- An ingress controller or API gateway configured to route traffic to the control plane (e.g. Istio, Nginx, ALB, etc.)
- Kubernetes secrets or secret-management flow for integration credentials
- Optionally, a preexisting Postgres database
What the Helm Chart Configures
The Helm install configures these main concerns:- Control plane deployment, service account, probes, and service
- RBAC for creating and managing session workloads, including a per-session service account
- A ClusterRole that lets the control plane read the cluster’s service account signing keys, used to authenticate session pods
- Embedded PostgreSQL for development, or an external database via
externalDatabase.existingSecret - Secret wiring for integrations and auth
Set up DNS
Cake Agent’s control plane needs to be reachable at a stable DNS name. This is used for user linking flows and should match thecontrolPlane.host
value in the Helm chart.
Choose a Database Strategy
For development, the chart defaults to embedded PostgreSQL. For shared or production-like environments, use an external database and provide a secret instead:Set up an auth client
Cake Agents uses OIDC for authentication. You can use any compliant provider, or delegate auth to an authenticating proxy via trusted headers. In your OIDC provider, create a new client with these settings:- Client type: Confidential
- Redirect URI:
https://<controlPlane.host>/api/auth/callback/oidc - Scopes:
openid email profile
Minimal Values File
Start from a small values file and expand from there:Install with Helm
Cake publishes release versions of the chart to a public registry atoci://public.ecr.aws/kflow/charts/cake-agents. You don’t need to authenticate to pull the chart. To inspect a release before you install it, run:
image.tag to the matching release image tag by default. For example, chart 0.5.0 deploys the 0.5.0 images. You don’t need to set image.tag in your values file. Set image.tag or a component-specific tag such as controlPlane.image.tag only when you need to run different images than the chart release.
Only the chart is public. By default, the chart pulls container images from Cake’s private registry at 684117700585.dkr.ecr.us-east-2.amazonaws.com. Your cluster nodes need permission to pull from that registry. Alternatively, mirror the images and override registry.default or the component-specific image registries, such as controlPlane.image.registry, in your values file.
Once you’re installed, you’ll need to configure your ingress or gateway to route traffic to the control plane service. If using Istio, you can enable the built-in gateway configuration in the chart and point your DNS at the gateway’s external IP.
After you can reach the control plane in the browser, you’re ready to set up integrations:
Session pod authentication
Session pods authenticate to the control plane with per-session service account tokens. See Data plane authentication for how this works. Withrbac.enabled: true, the chart grants everything this needs. If you set rbac.enabled: false and manage RBAC yourself, grant the control plane service account:
create,get,list,watch,update,patch, anddeleteonserviceaccountsin the session namespacegeton the non-resource URLs/.well-known/openid-configurationand/openid/v1/jwks
jwks_uri your kube-apiserver advertises. On some clusters, such as EKS, this is a public HTTPS endpoint outside the cluster. Make sure egress rules let the control plane reach it.
When you upgrade from a version without per-session service accounts, the control plane migrates running sessions at startup. It creates each session’s service account and updates the session’s StatefulSet, which restarts the pod. The session’s workspace volume and OpenCode state persist across the restart.
Optional: S3 object storage
The control plane can optionally use an S3-compatible bucket for object storage. This is disabled by default; enable it when a feature you use requires durable object storage. Set thes3.* values to bootstrap the connection:
- An IAM role attached to the control plane service account (IRSA on EKS, Workload Identity on GKE)
- Standard
AWS_ACCESS_KEY_ID/AWS_SECRET_ACCESS_KEYenv vars supplied viacontrolPlane.deployment.extraEnv
s3.region or s3.endpoint are unset, the control plane also accepts the standard AWS_REGION and AWS_ENDPOINT_URL_S3 env vars.
Optional: Session pod resources
Each session runs in its own data plane pod. By default, the control plane sets these resources on every session container:- A
1Gimemory request and a250mCPU request, so the Kubernetes scheduler places sessions on nodes with enough headroom. - A
16Gimemory cap and a3CPU limit, so one runaway session can’t consume an entire node. Each session starts with a memory limit equal to its memory request. The agent can raise the limit up to the cap and lower it back down to the request. See Automatic memory resizing. - A
1Giephemeral storage request and a10Giephemeral storage limit, which cap how much node-local disk a session can use.
dataPlane.resources to change this. The value accepts a full Kubernetes resource requirements block, so you can set both requests and limits:
2Gi memory limit. The agent can raise it to 12Gi.
Memory and CPU changes apply to sessions created after the Helm upgrade. Existing session pods keep the memory and CPU they were created with.
Session memory and CPU limits
If a session uses more memory than its current memory limit, Kubernetes stops and restarts the session container. This is called an OOM kill (out of memory). The pod, session volume, and files in/workspace are kept. If the agent was mid-turn, it resumes automatically after the restart.
If a session reaches limits.cpu, Kubernetes slows it down instead of stopping it. If heavy builds feel slow, raise or remove limits.cpu first.
Always set a memory and CPU request alongside each limit. If you set only a limit, Kubernetes uses the limit as the request. The scheduler then reserves the full limit for every session, which reduces how many sessions fit on each node.
The CPU request reserves capacity on each node. Raising requests.cpu or requests.memory lowers the number of sessions that fit on a node.
Automatic memory resizing
The agent can change its own session’s memory limit. It raises the limit when a command runs out of memory. It lowers the limit to give memory back to the cluster, for example after a memory-heavy job finishes. The agent uses two tools from the Cake MCP server:session_memory_statusreports the current memory limit, the cap, and whether a resize is in progress. It doesn’t change anything.memory_limitsets the memory limit to a target size. The agent must passtargetMemoryGib, a whole number of GiB from1to64. The control plane compares the target with the current limit and raises or lowers it to match.
- Raises stop at the memory cap.
- Lowers stop at the session’s memory request (
dataPlane.resources.requests.memory). A limit can’t go below its request.
rbac.enabled: false, also grant the control plane service account patch on pods/resize in the session namespace.
Raise the memory limit
A raised limit applies within seconds. In-place resize requires Kubernetes 1.33 or later. If the cluster doesn’t support it, or the node can’t fit the larger limit, the control plane replaces the pod with the new limit instead. The new pod may run on a different node. The session restarts briefly, and its volume and files are kept. A raised limit doesn’t always survive a pod restart. The control plane writes it into the session’s pod spec only when the pod is already being replaced. Until then, a replaced pod comes back at the previous limit, and the agent can request more memory again.Lower the memory limit
Lowering a memory limit in place requires Kubernetes 1.35 or later. A lower limit applies once the session’s current memory usage is below it. Until then, the kubelet holds the resize as pending and keeps retrying. The tool reports this as a pending resize, not an error. After a lower, commands that need more memory than the new limit are OOM killed. The agent can raise the limit again with the same tool. Kubernetes rejects a lower limit in these cases:- The cluster runs Kubernetes 1.34 or earlier.
- Session pods use the Guaranteed QoS class, meaning every CPU and memory request equals its limit. The default session resources use different CPU request and limit values, so session pods are Burstable.
Set the memory cap
The memory cap is the largest memory limit a session can grow to. By default, the cap isdataPlane.resources.limits.memory from your Helm values. Raising the cap doesn’t change what the scheduler reserves for each session. The scheduler only reserves requests.memory.
Organization admins can override the cap without a Helm upgrade:
- Go to Settings → Organization → Sessions.
- In Max Memory, enter a whole number and select Mi or Gi.
- Select Save.
dataPlane.resources.limits.memory. If you raise it, make sure your nodes have enough memory for the larger limits.
Session disk limit
Ephemeral storage is node-local disk that a session uses outside its persistent session volume. It covers/tmp, tools installed into system directories, and container logs. Files in /workspace and the home directory (/root) live on the session volume and don’t count toward the limit.
Package manager caches such as ~/.npm and ~/.cache are in the home directory, so they use the session volume’s space instead of node disk. Heavy caches can fill the session volume. Enable session volume autoscaling to grow it automatically.
If a session goes over limits.ephemeral-storage, Kubernetes evicts that session pod. This stops one runaway session from filling the node’s disk and affecting other sessions. Kubernetes checks disk usage periodically, so a session that writes very quickly can briefly exceed the limit before eviction.
To change the limit, override the ephemeral-storage entries:
requests.ephemeral-storage together with the limit, and keep the request well below it. If you set only a limit, Kubernetes uses the limit as the request. The scheduler then reserves the full limit for every session, which reduces how many sessions fit on each node.
The control plane applies ephemeral storage changes to running sessions when it starts.
Upgrading to a release that moves the home directory onto the session volume also restarts every running session pod once. Files in
/workspace, session history, and attachments are kept. Files the agent previously wrote to /root aren’t carried over.Interrupted agent turns
A session container can restart while the agent is working. This happens after an OOM kill, an eviction, or an upgrade that restarts session pods. When the container starts again, Cake Agents checks whether the session’s last agent turn finished. If it didn’t, Cake Agents sends the agent a hiddencontinue prompt so it picks up where it stopped. You don’t need to configure anything.
Cake Agents doesn’t resume a turn in these cases:
- The turn finished before the restart, or a user stopped it.
- Someone sent a new message after the interrupted turn.
- The session already resumed 3 times in a row without completing a turn. This stops a session that crashes repeatedly from restarting the same work in a loop. The count resets after a turn completes.
Optional: Session pod scheduling
By default, Kubernetes can schedule session pods on any node in the cluster. UsedataPlane.nodeSelector and dataPlane.tolerations to run sessions on a dedicated group of nodes. For example, you can keep sessions apart from other workloads or give them their own Karpenter node pool.
dataPlane.nodeSelectoris a map of node labels. Kubernetes places session pods only on nodes that have every listed label.dataPlane.tolerationslists tolerations that let session pods run on tainted nodes. Each entry takes a requiredkeyand optionaloperator,value, andeffect.
These values apply only to session pods. To schedule the control plane, use
controlPlane.nodeSelector and controlPlane.tolerations.
Optional: Kubernetes API access from sessions
By default, session pods can’t call the Kubernetes API. Turn this on when you want session agents to inspect the cluster they run in. For example, an agent can read pod logs while debugging a Cake Agents deployment. Access has two parts:dataPlane.automountServiceAccountTokenmounts a standard Kubernetes token in each session pod. Tools likekubectlfind it at the default path,/var/run/secrets/kubernetes.io/serviceaccount.dataPlane.roleslists existing Roles or ClusterRoles that grant permissions to that token. On its own, the token can’t do anything.
namespace to grant access outside the session namespace. Ending a session deletes its RoleBindings. When the control plane starts, it also adds newly listed roles to running sessions, without restarting them.
With an empty
roles list, the control plane makes no RoleBinding API calls. Session authentication to the control plane works the same way whether or not you enable this feature.
Grant the control plane permission to bind roles
The chart doesn’t create the listed roles. It also doesn’t give the control plane permission to bind them. Before you list a role:- Create the Role or ClusterRole in the cluster, outside the Cake Agents release.
- Give the control plane service account
create,get,list, anddeleteonrolebindingsin every target namespace. - Give the control plane
bindon each listed role, limited withresourceNames.
bind on it. A bind grant limited by resourceNames restricts the control plane to exactly the roles you list:
403 Forbidden response, session creation fails. The control plane validates dataPlane.roles at startup and refuses to start when an entry is malformed or two entries resolve to the same role and namespace.
Under a
bind grant, Kubernetes doesn’t check that the referenced role exists. A misspelled role name creates a RoleBinding that grants nothing, without an error. Check that each role exists in its target namespace. The control plane logs every RoleBinding it creates with its role reference.Optional: Additional volumes in session pods
UsedataPlane.additionalVolumes and dataPlane.additionalVolumeMounts to mount extra Kubernetes volumes into every session pod. A common use is giving session agents credentials for an external service. For example, you can mount an EKS IAM roles for service accounts (IRSA) token so in-session tools can assume an AWS role.
dataPlane.additionalVolumestakes a list of standard Kubernetes volumes. Any volume type works, such asprojected,configMap, orsecret. Each entry needs aname.dataPlane.additionalVolumeMountstakes a list of standard Kubernetes volume mounts. Each entry needs anamethat matches a declared volume and an absolutemountPath.readOnlyand the other volume mount fields are optional.
serviceAccountToken source issues a token for the session’s own service account, bound to the audience you set.
At startup, the control plane checks only the shape of each entry. Kubernetes validates everything else. If Kubernetes rejects a volume or mount, session provisioning fails with a
422 response and the control plane logs the error.
Changing either list restarts every running session pod once, the next time the control plane starts. Removing an entry removes its volume and mount from running sessions. With both lists empty, session pods are identical to a deployment without this option.
Kubernetes doesn’t catch these mistakes, so check for them yourself:
- Don’t name a volume with the
kube-api-access-prefix. Kubernetes treats it as the automounted cluster token volume, anddataPlane.automountServiceAccountTokenstops working without an error. - Don’t use the Cake Agents internal authentication audience in a
serviceAccountTokensource. That mounts the session’s internal token with a longer validity window than Cake Agents allows. - Avoid mount paths under
/root,/workspace, or/attachments. A nested mount hides that part of the session’s files. - Don’t mount under
/var/run/secrets/cake.ai/serviceaccount. The session pod starts without working internal integrations, and a pod log warning is the only signal.
Optional: Kubernetes API rate limits
The control plane limits how fast it sends requests to the Kubernetes API server. This keeps a busy control plane from overloading a shared cluster. The defaults match the Kubernetes Go client (client-go): 5 requests per second, with bursts of up to 10.
Raise the limits if session startup or status updates lag on a large cluster that can handle more traffic. Lower them if the API server is shared and other workloads see throttling. Set them with environment variables in controlPlane.deployment.extraEnv:
Each control plane replica applies these limits separately. The total load on the API server is the limit multiplied by the number of replicas. The control plane fails to start if either value is below its minimum.
When the API server responds with
429 Too Many Requests, the control plane retries the request automatically:
- It waits for the duration in the
Retry-Afterheader when one is present. Otherwise, it backs off exponentially from 500 ms up to 30 seconds. - It retries each request up to 10 times, and waits no more than 60 seconds in total.
- While it has received a
429in the last 60 seconds, it halves both limits. The limits never drop below 0.5 requests per second and a burst of 1. Full limits return once 60 seconds pass without a429.
5xx responses that include a Retry-After header. If a session update still fails after these retries, the control plane logs the error and continues with other sessions. The failed update is retried later, as described in Session updates at startup.
Session updates at startup
When the control plane starts, for example after an upgrade, it checks every running session and updates any session pod whose configuration is out of date. Cake Agents queues these updates as background jobs and processes them in small batches. Running them in batches stops an upgrade from restarting every session pod at once and flooding the Kubernetes API server.
Like the rate limits above, these limits apply to each replica separately. Lower the concurrency or raise the delay to restart fewer session pods at once. Raise the concurrency to finish upgrades faster on clusters with spare capacity. The control plane fails to start if either value is out of range.
If a session update fails, Cake Agents retries it with exponential backoff, starting at 30 seconds. It retries up to 8 times, with at most 15 minutes between attempts. You don’t need to restart the control plane to retry failed updates.
Session updates pause while the Kubernetes API server is rate-limiting the control plane. If the control plane has received a
429 in the last 60 seconds, each queued update waits before it calls the API server. Updates resume once 60 seconds pass without a 429. During a long pause, the control plane logs a warning every 60 seconds.
Optional: Custom sign-out URL
By default, when a user selects sign out in the web UI, Cake Agents ends the user’s session and returns them to the Cake Agents sign-in page. If you delegate auth to an authenticating proxy such as oauth2-proxy withheaderAuth, the proxy’s own session stays active. The user is signed straight back in on the next request.
Set controlPlane.signOutUrl to send users to your proxy’s sign-out endpoint instead:
- Relative paths are resolved against the public origin of the control plane. A full URL also works.
- For oauth2-proxy, include the
rdquery parameter to set where the proxy sends the user after sign-out. Withoutrd, the browser loops on/oauth2/sign_out. - If you serve Cake Agents under a
pathPrefix, pointrdat that path, for example/oauth2/sign_out?rd=/cake-agents/.
signOutUrl empty to keep the default behavior.
Optional: Disable public ingress
Setingress.publicServices.enabled to false when external services can’t reach your Cake Agents instance, such as in a private network or an air-gapped cluster. The default is true.
- renders no Istio
Gateway,VirtualService, or ingress-gatewayAuthorizationPolicyresources - removes the Istio ingress gateway from the allowed callers of the web and storybook workloads
- disables external webhooks in Cake Agents
- GitHub: The GitHub App manifest registers no webhook and subscribes to no events. Cake Agents doesn’t sync the App’s webhook configuration. Agents can’t subscribe to GitHub webhook events and poll CI with the
ghCLI instead. - Linear: The Linear OAuth app manifest has no webhook, and the Webhook Secret field is hidden. Linear can’t start Cake sessions, so invoking the Cake agent on a Linear issue has no effect.
- Slack: The Slack app manifest has no event subscriptions. Cake Agents returns
404for incoming Slack events.
Values Reference
Ingress authorization policies
Whenistio.enabled is true, the chart always creates in-namespace AuthorizationPolicy resources that restrict traffic to the control plane pods (allowing the Istio ingress gateway and same-namespace callers).
By default, istio.authorizationPolicy.create is true, so the chart also creates the ingress-side policies in the istio-system namespace: an ALLOW policy that scopes traffic to your controlPlane.host and pathPrefix, and a CUSTOM policy that routes authenticated paths through oauth2-proxy while leaving webhook endpoints (Linear, Slack, setup finalize) open.
Set istio.authorizationPolicy.create to false if another controller in your cluster already provisions these policies for the control plane host, or if you manage ingress-side authorization outside the chart.